Upgrade to Pro
— share decks privately, control downloads, hide ads and more …
Speaker Deck
Sign up for free
Menu
Search
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Pricing
Search
Sign in
Sign up for free
生成AIなんでも展示会vol6 LT登壇資料 NexteraBERT
Search
Sponsored
·
Your Podcast. Everywhere. Effortlessly.
Share. Educate. Inspire. Entertain. You do you. We'll handle the rest.
→
Rikka Botan
September 23, 2026
Research
160
0
Share
Embed
Copy iframe code
Copy JS code
Copy link
Start on current slide
生成AIなんでも展示会vol6 LT登壇資料 NexteraBERT
生成AIなんでも展示会 vol.6での登壇資料です。
Rikka Botan
September 23, 2026
More Decks by Rikka Botan
See All by Rikka Botan
HackSick vol.7 LT資料【LLMアーキテクチャ入門・事前学習時の躓き所解説】 スパースなAttention・状態空間モデル
rikkabotan7
0
200
【ローカルAIに向き合う展示会vol.2】液体時間定数型モジュールを用いた オリジナルの双方向エンコーダーモデルNexteraBERT 推論速度向上検討並びにダウンストリーム評価
rikkabotan7
0
220
【生成AIなんでも展示会vol.5 LT登壇】NexteraBERT発表資料
rikkabotan7
1
230
SSE: Stable Static Embedding
rikkabotan7
0
45
【ローカルAI LT大会】SSE: Stable Static Embedding ー速度低下を伴わず 静的埋め込みモデルの潜在能力を引き出す Dynamic Tanh手法の提案
rikkabotan7
0
120
SEA Model series Op.1: Saint Lupinus pre-release
rikkabotan7
0
160
Other Decks in Research
See All in Research
PGDM: Physically Guided Diffusion Model for L Downscaling
satai
3
500
J-STAGEの現況と全文XML登載必須化について
xspa2012
0
290
Language and AI
ayaniwa
0
310
進化?迷走?CasualConc ファミリーアプリの現在地 @ 英語コーパス学会 2026
casualconc
0
110
[最先端NLP勉強会2026] Agentic Rubrics as Contextual Verifiers for SWE Agents
rfujii
1
370
Visual SLAM未来予測 / Future Prediction in Visual SLAM
koide3
1
1.1k
学術バーQ AI研究最前線:自己教師あり学習による画像モデルの事前学習
naok615
0
120
IA for theory
gpeyre
1
440
RS-Agent: Automating Remote Sensing Tasks through Intelligent Agent
satai
3
580
長時間動画QAにおけるマルチエージェント推論 ・SVAgent: Storyline-Guided Long Video Understanding via Cross-Modal Multi-Agent Collaboration
murakawatakuya
1
210
[ACL 2026 Demo] Fast-MIA: Efficient and Scalable Membership Inference for LLMs
upura
0
130
SLAMはどこまで解決されたのか?
tomonom
0
1.4k
Featured
See All Featured
How to Ace a Technical Interview
jacobian
280
24k
Facilitating Awesome Meetings
lara
57
7.2k
BBQ
matthewcrist
89
10k
How to Create Impact in a Changing Tech Landscape [PerfNow 2023]
tammyeverts
56
3.5k
Skip the Path - Find Your Career Trail
mkilby
1
240
Hiding What from Whom? A Critical Review of the History of Programming languages for Music
tomoyanonymous
3
1.3k
Scaling GitHub
holman
464
140k
Avoiding the “Bad Training, Faster” Trap in the Age of AI
tmiket
0
250
For a Future-Friendly Web
brad_frost
183
10k
The Web Performance Landscape in 2024 [PerfNow 2024]
tammyeverts
12
1.3k
Money Talks: Using Revenue to Get Sh*t Done
nikkihalliwell
0
510
Heart Work Chapter 1 - Part 1
lfama
PRO
10
36k
Transcript
わたしのこだわりは、知の架橋と知の転換です
NexteraBERT: Input-Dependent Gating Liquid Mixer and Length-Adaptive Attention for Fast,
Long-Context Bidirectional Encoders 入力依存型Liquid Mixerと長さ適応型Attentionによる 高速な長文対応双方向エンコーダ
Vol.6 生成AIなんでも展示会
自己紹介 / About us り っ か 六花 ぼ た
ん 牡丹 Rikka Botan 独立研究者(機械学習 / 代数学 / 数理論理学) Independent researcher (machine learning / algebra / mathematical logic) ◆趣味 お菓子作り・紅茶・クラシック鑑賞・お洋服 ◆最近の活動 Silver Award: Liquid AI Hackathon Series | Tokyo 記事執筆(Mamba, LFM2 (LTCs) 関連) SSE Modelシリーズの公開 X(Twitter) Portfolio
目録 / Contents 1 主な貢献 / Main Contributions 2 知の架橋
/ Bridging Knowledge 3 知の転換 / A Shift in Thinking 4 経験のユニーク性 / The Uniqueness of Experience
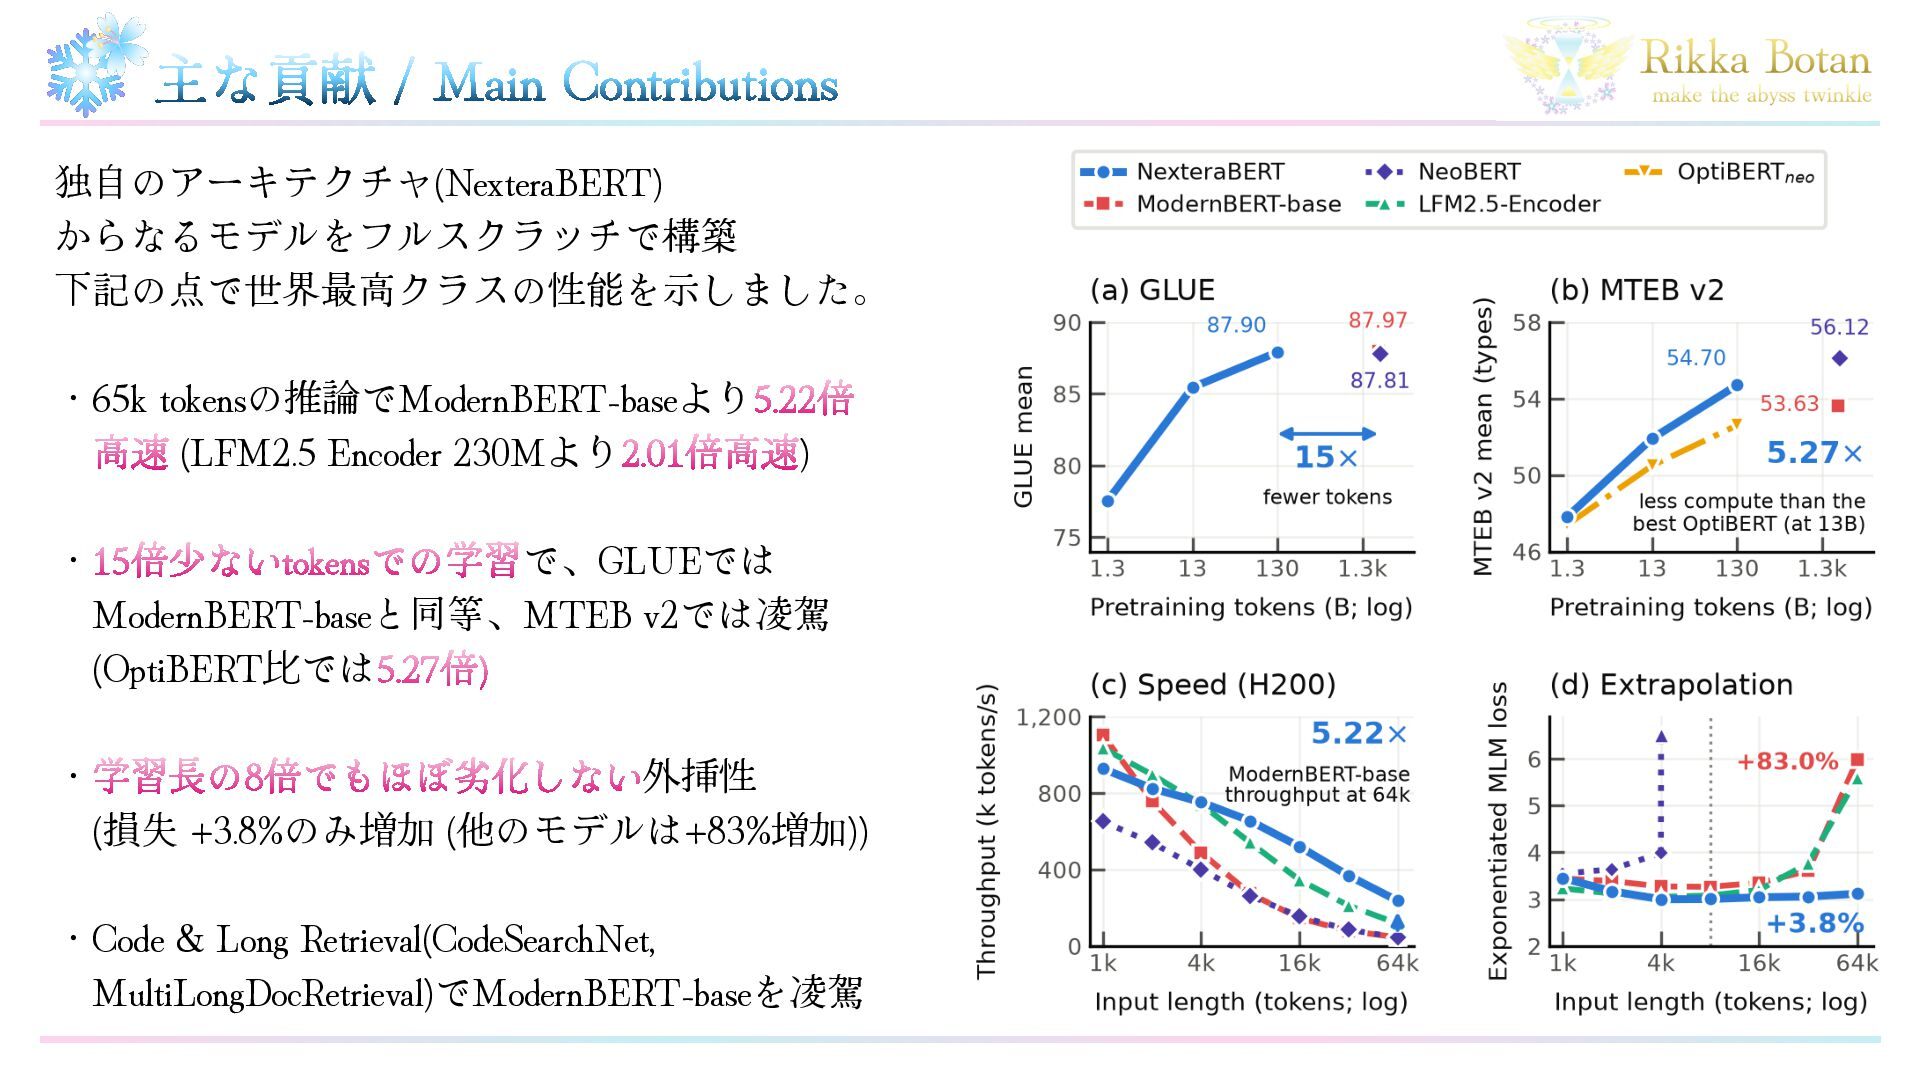
主な貢献 / Main Contributions 独自のアーキテクチャ(NexteraBERT) からなるモデルをフルスクラッチで構築 下記の点で世界最高クラスの性能を示しました。 ・65k tokensの推論でModernBERT-baseより5.22倍 高速
(LFM2.5 Encoder 230Mより2.01倍高速) ・15倍少ないtokensでの学習で、GLUEでは ModernBERT-baseと同等、MTEB v2では凌駕 (OptiBERT比では5.27倍) ・学習長の8倍でもほぼ劣化しない外挿性 (損失 +3.8%のみ増加 (他のモデルは+83%増加)) ・Code & Long Retrieval(CodeSearchNet, MultiLongDocRetrieval)でModernBERT-baseを凌駕
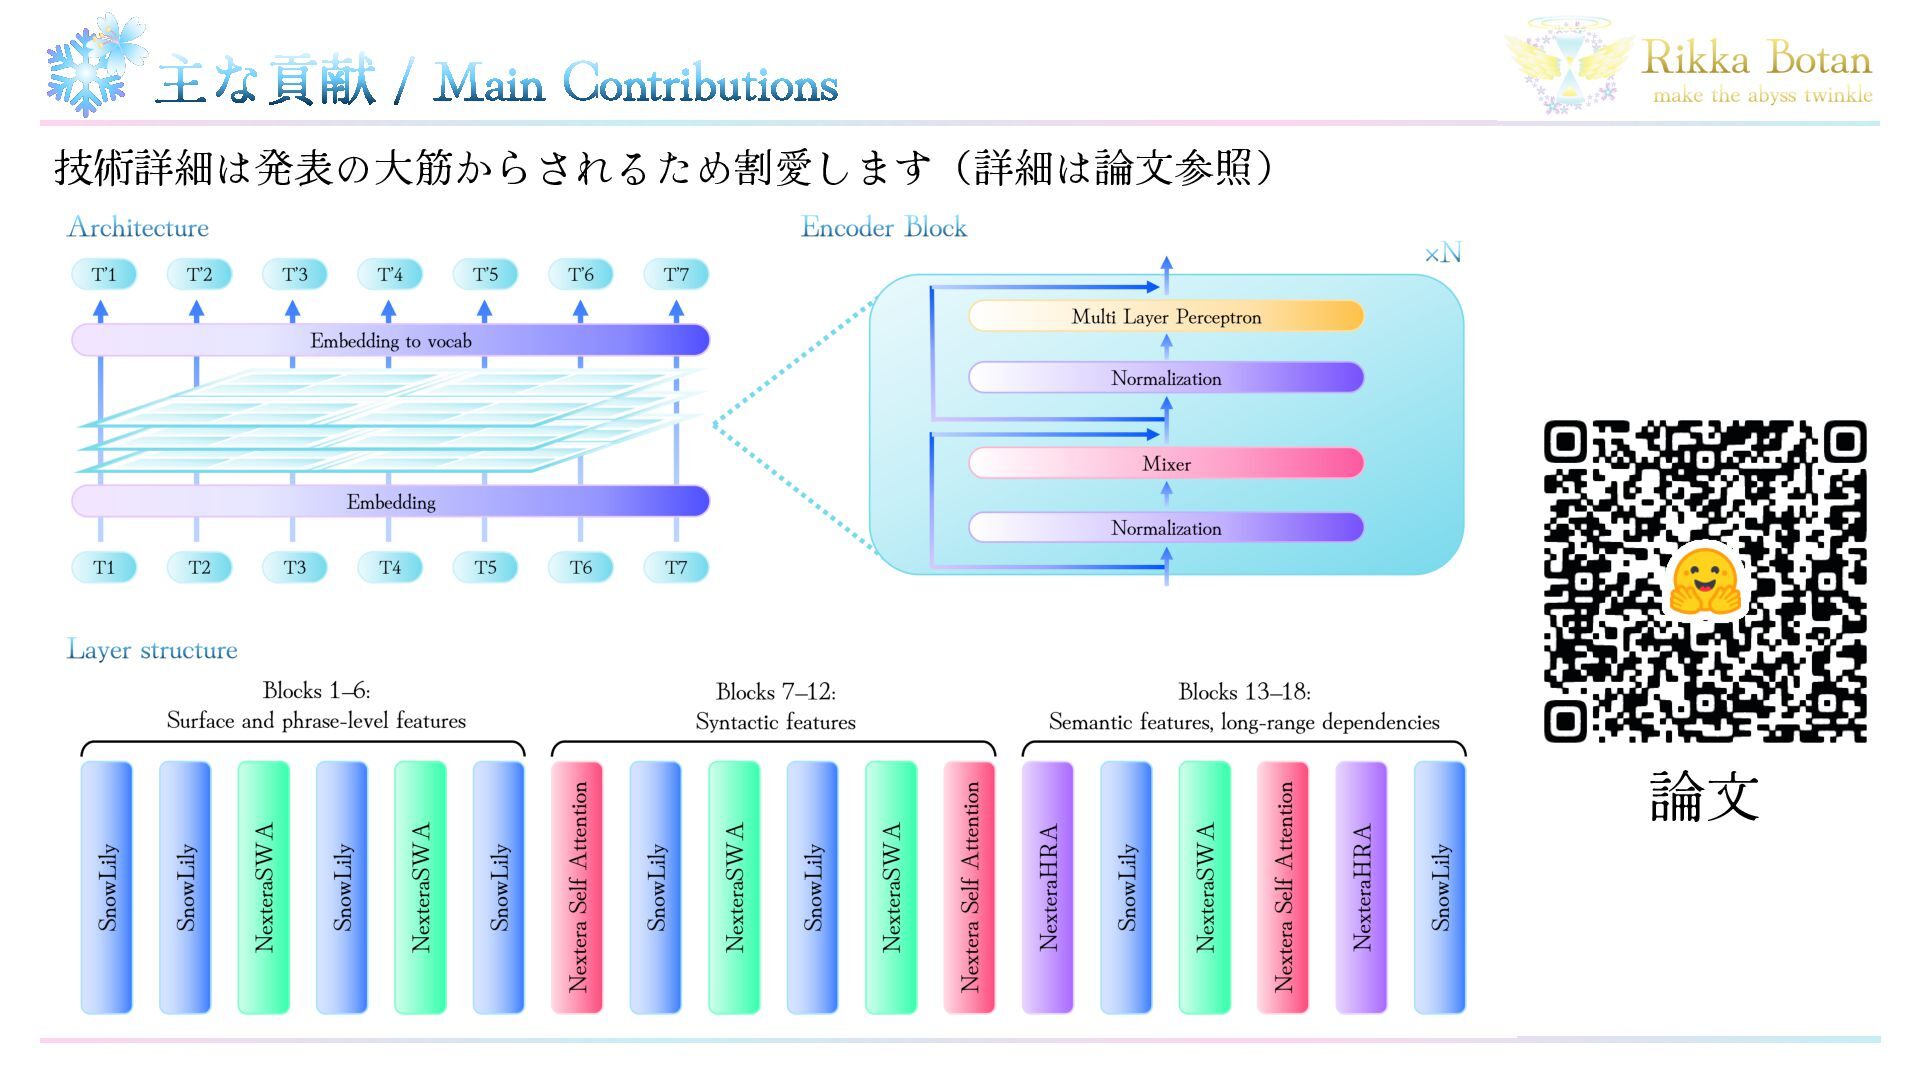
主な貢献 / Main Contributions 技術詳細は発表の大筋からされるため割愛します(詳細は論文参照) 論文
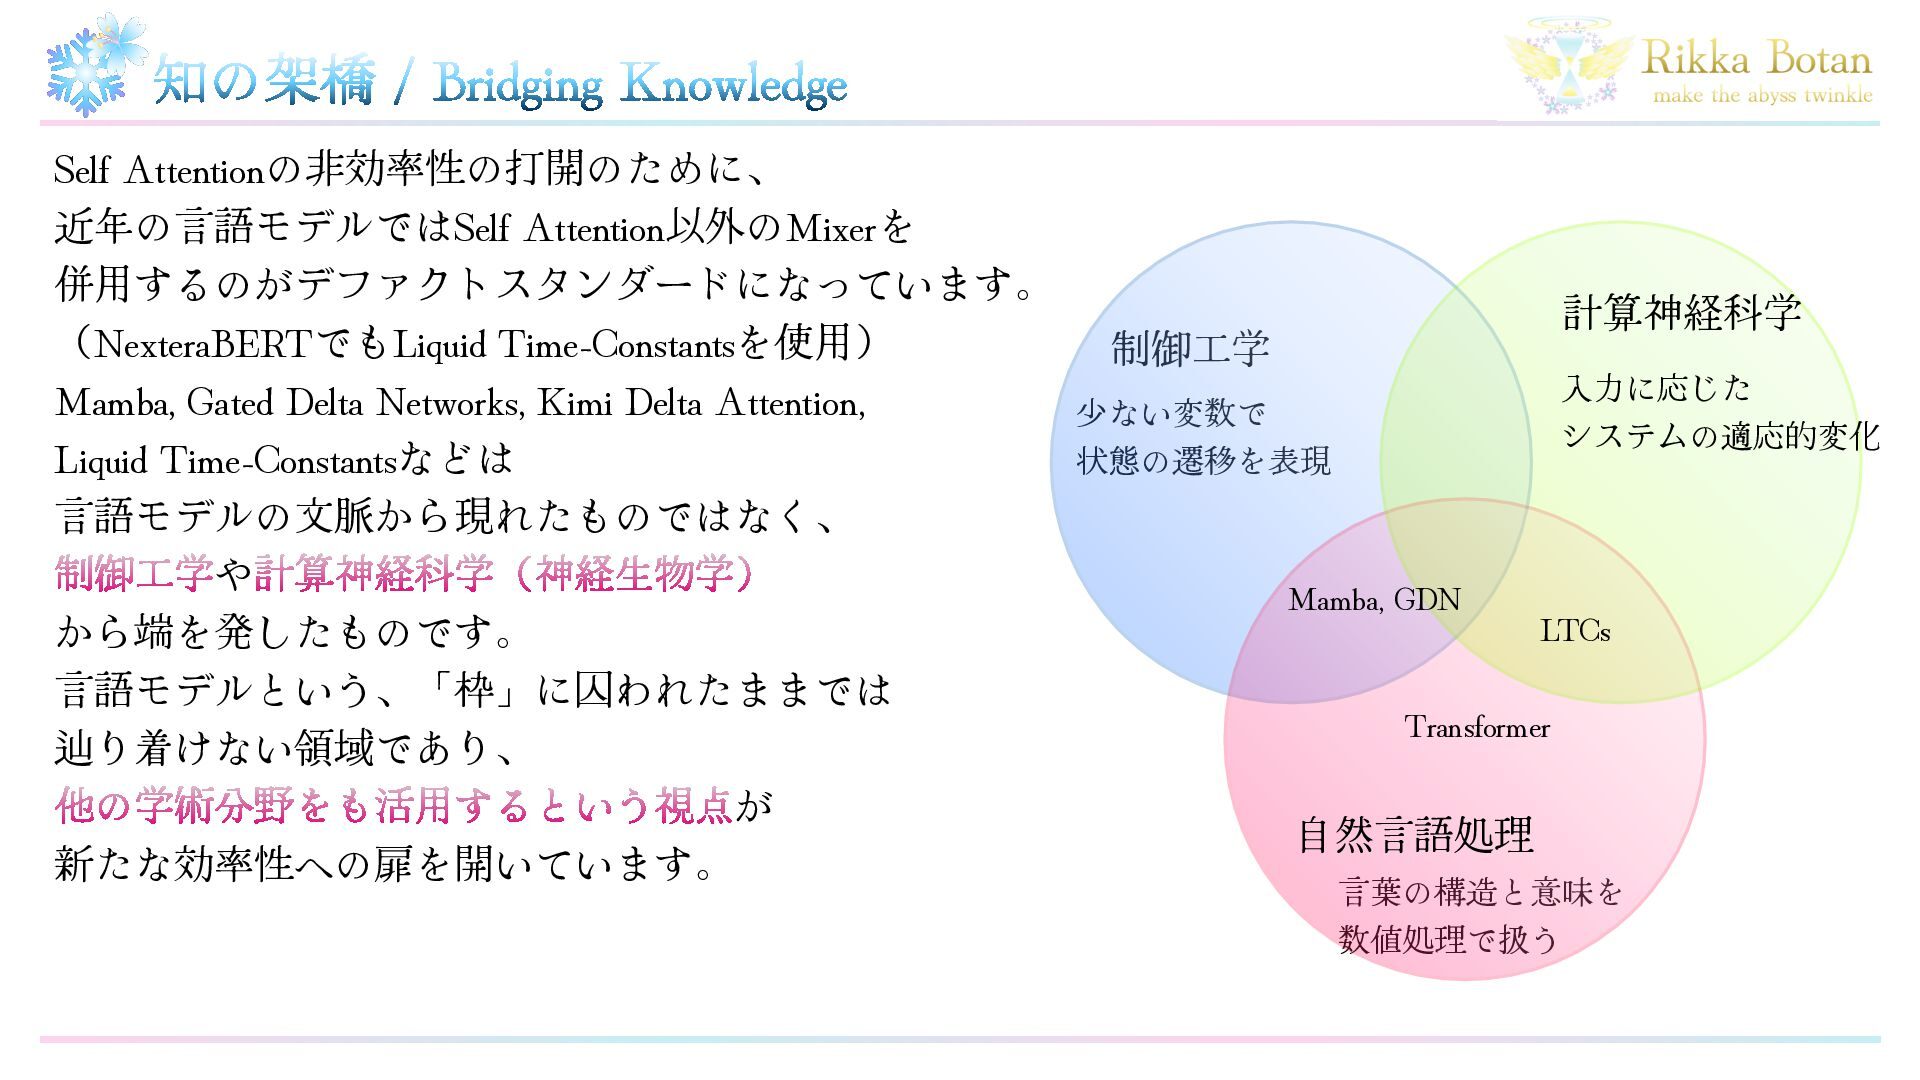
知の架橋 / Bridging Knowledge Self Attentionの非効率性の打開のために、 近年の言語モデルではSelf Attention以外のMixerを 併用するのがデファクトスタンダードになっています。 計算神経科学
(NexteraBERTでもLiquid Time-Constantsを使用) 制御工学 入力に応じた Mamba, Gated Delta Networks, Kimi Delta Attention, 少ない変数で システムの適応的変化 Liquid Time-Constantsなどは 状態の遷移を表現 言語モデルの文脈から現れたものではなく、 制御工学や計算神経科学(神経生物学) Mamba, GDN LTCs から端を発したものです。 言語モデルという、「枠」に囚われたままでは Transformer 辿り着けない領域であり、 他の学術分野をも活用するという視点が 自然言語処理 新たな効率性への扉を開いています。 言葉の構造と意味を 数値処理で扱う
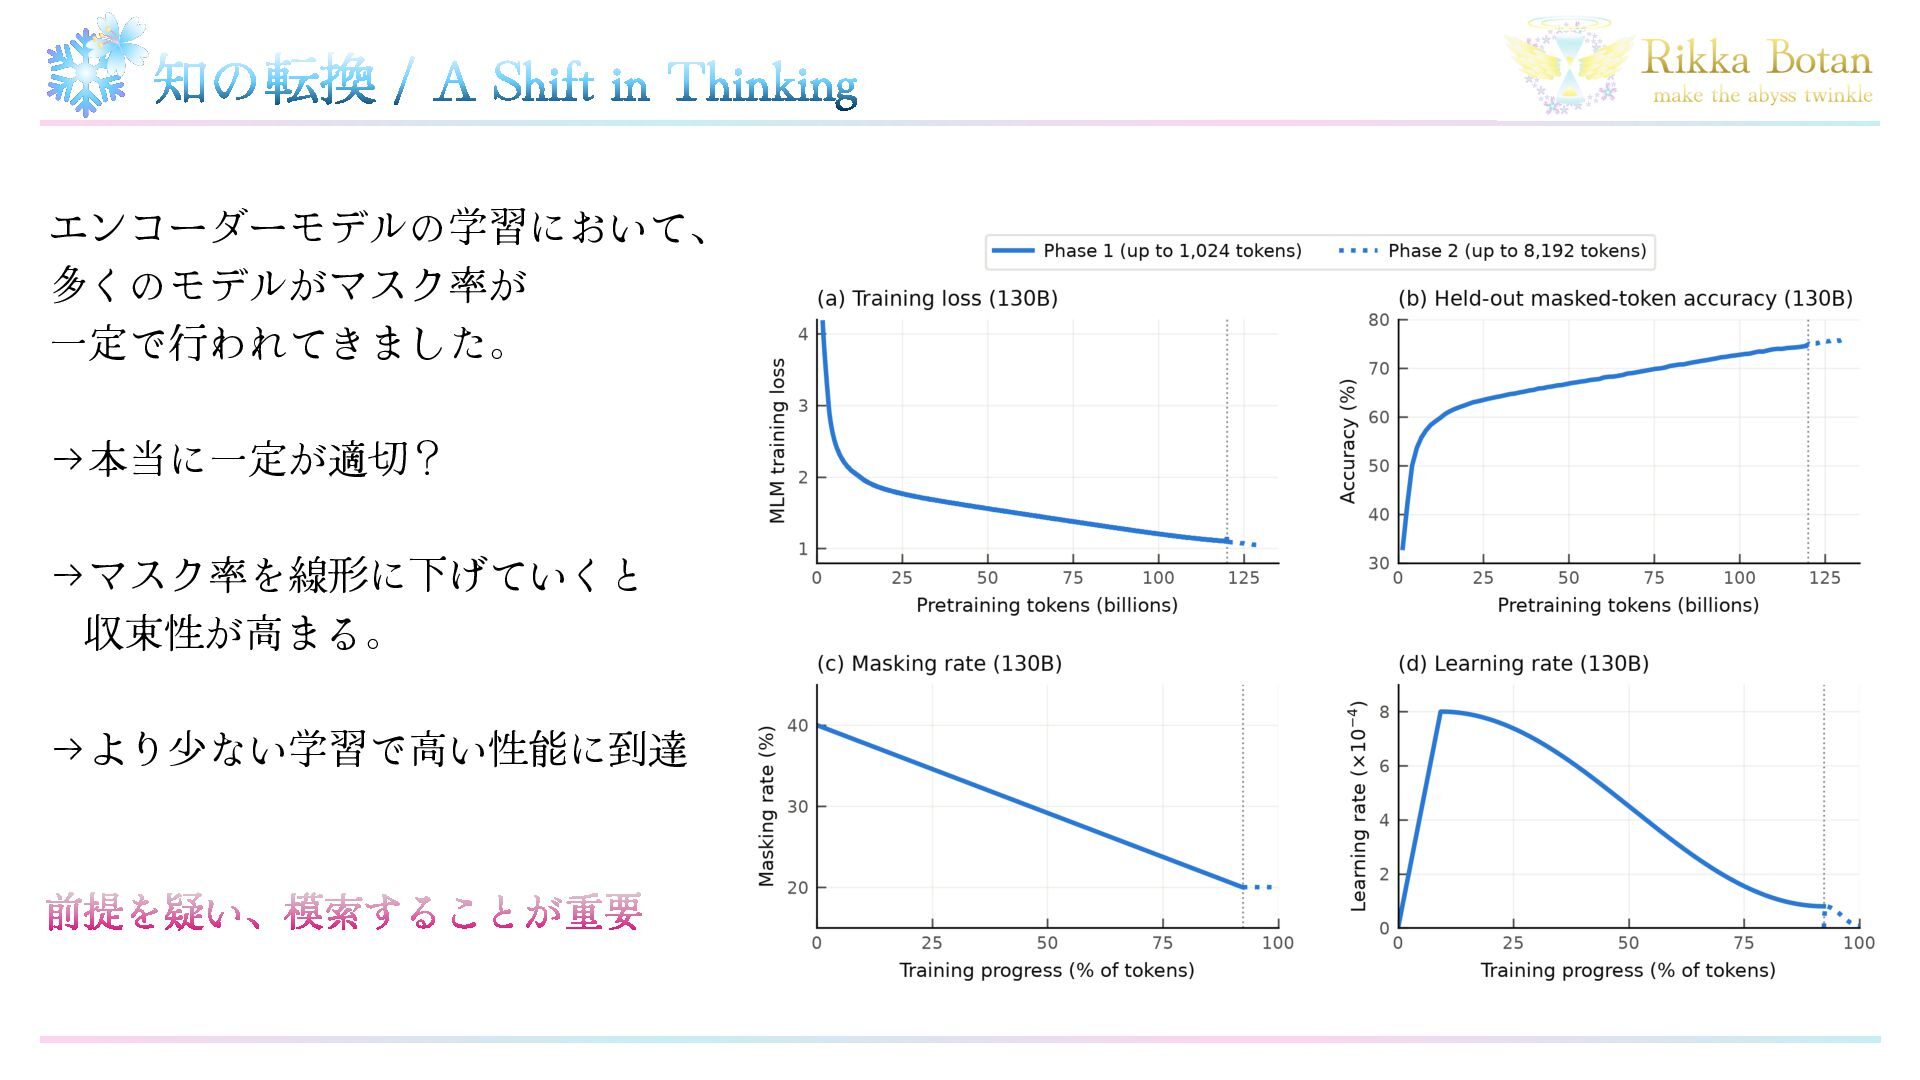
知の転換 / A Shift in Thinking エンコーダーモデルの学習において、 多くのモデルがマスク率が 一定で行われてきました。 →本当に一定が適切?
→マスク率を線形に下げていくと 収束性が高まる。 →より少ない学習で高い性能に到達 前提を疑い、模索することが重要
経験のユニーク性 / The Uniqueness of Experience 遠回りだと思っていた経験が、 成果につながりました。 知を架橋するには、二つ以上の分野を知っている必要があります。 前提を疑うには、その前提の外側を知っている必要があります。
(例えば私は以前、制御工学を学んでいてその視点を少し持っていました。)
経験のユニーク性 / The Uniqueness of Experience あなたの経験の組み合わせは あなたにしかないものです。 あなただけの見方で作った 面白い世界を見せてください。
12


 rikkabotan7
.png) satai
 xspa2012
 ayaniwa
 casualconc
 rfujii
 koide3
 naok615
 gpeyre
 murakawatakuya
 upura
 tomonom
 jacobian
 lara
 matthewcrist
 tammyeverts
 mkilby
 tomoyanonymous
 holman
 tmiket
 brad_frost
 nikkihalliwell
 lfama